Automating a blog becomes fragile when one AI model handles every task and publishes without checks. AI model rotation offers a more controlled approach: select models for specific editorial jobs, evaluate replacements before deployment, and keep publishing permissions separate from text generation.
This guide explains how to build that workflow, from research and drafting to WordPress scheduling and model migrations. The goal is not to chase every new release; it is to create a publishing process that remains useful when models, APIs, source material, and editorial requirements change.
What AI model rotation means for blog publishing
AI model rotation is the controlled use or replacement of AI models within a publishing workflow. A model router assigns each task to an approved model, while editorial checks determine whether the resulting content can move toward publication. Rotation can happen between tasks, after a model update, or when an approved fallback is needed.
These situations are related, but they require different decisions. Sending title generation to a lightweight model is task routing. Replacing a retiring drafting model is migration. Redirecting a failed request to another approved model is failover.
- Task routing: Choose a model according to the difficulty, context needs, latency requirements, and consequences of a particular task.
- Version rotation: Replace an existing model after evaluating a newer version against your editorial requirements.
- Fallback routing: Use a tested alternative when the preferred model is unavailable or cannot complete an eligible task.
OpenAI’s model-selection guidance recommends starting with explicit model selection and matching the model to the job. That supports a deliberate publishing architecture rather than a workflow that sends every request to whichever model is newest.
For a blog, the distinction matters because creating topic tags is not equivalent to reviewing a technical explanation. A plausible-sounding tag has limited consequences; an unsupported product claim can undermine the entire article.
Rotate models according to the work they must perform, not simply because another model has appeared.
Rotation also does not require using several providers. You can begin with different approved models within one provider’s ecosystem, or maintain a primary model and a tested replacement. Cross-provider routing is an option when its benefits justify the additional integration and evaluation work.
Map the editorial workflow before choosing models
Start with the publishing process, not the model catalog. Write down the inputs, expected outputs, acceptance criteria, and permissions for every stage. Otherwise, a router merely distributes an unclear task across more systems.
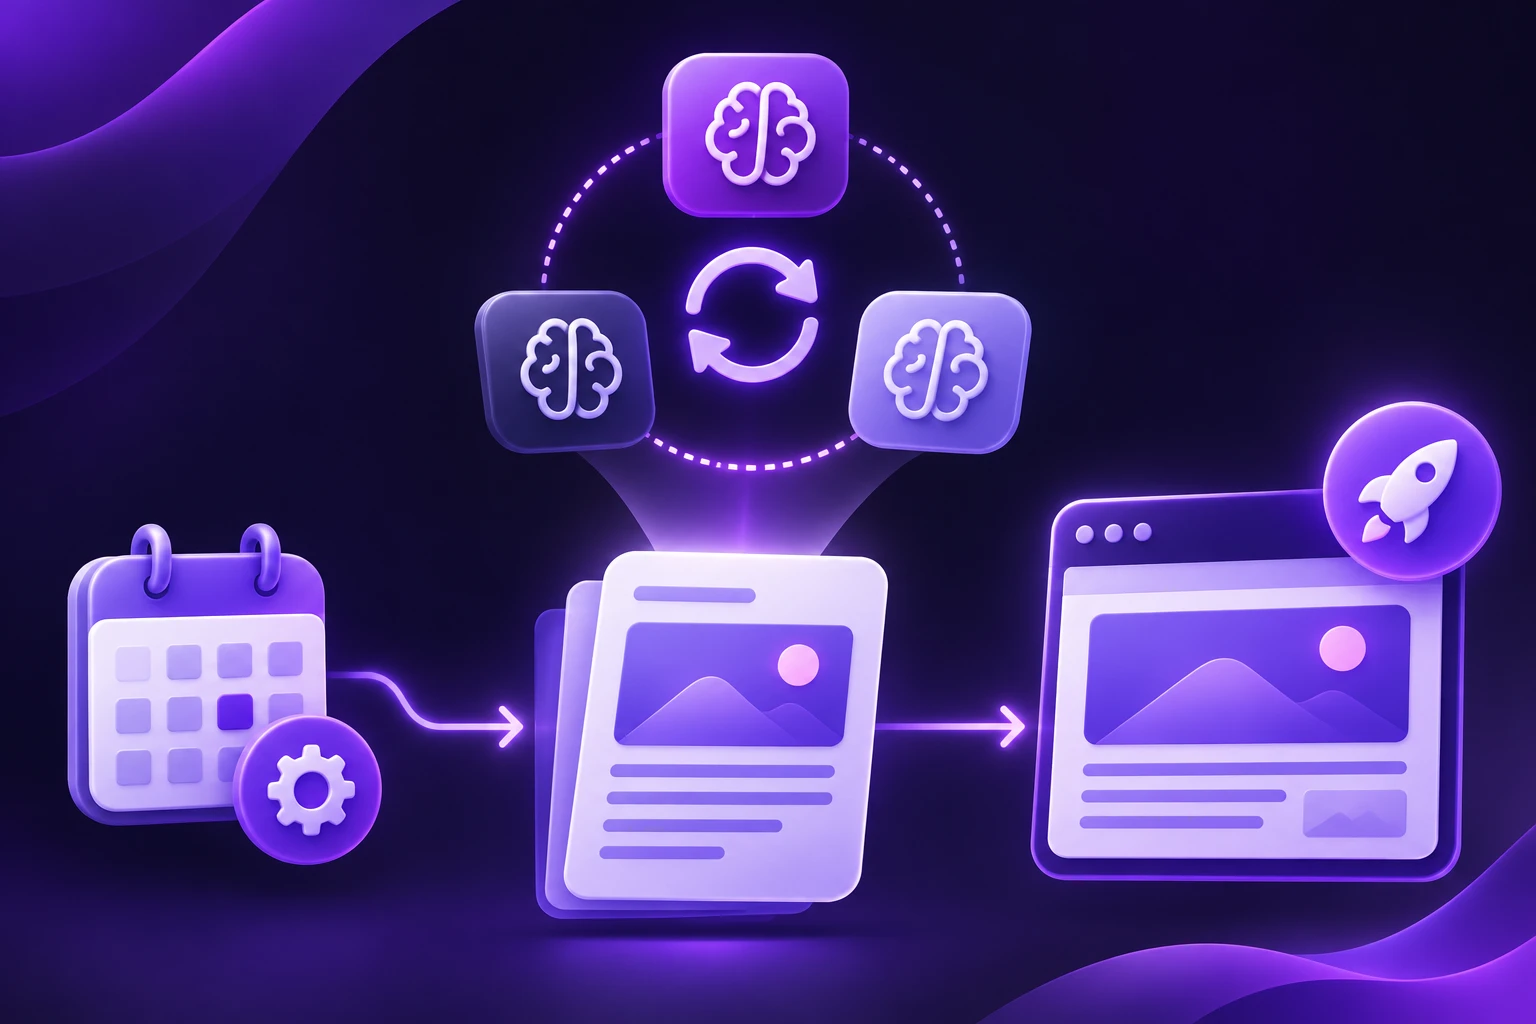
A practical workflow separates decisions that are often bundled into one long prompt. Research determines what can be claimed. Drafting organizes and explains those claims. Editing improves the article. Publication changes the state of your website.
- Create the brief. Define the reader, search intent, primary keyword, article purpose, required sections, and topics to exclude.
- Assemble approved evidence. Collect source excerpts, internal documentation, product specifications, or other material the article is allowed to use.
- Build the outline. Arrange the reader’s questions into a useful sequence and identify where evidence is needed.
- Generate the draft. Write within the brief and evidence boundaries, marking missing support instead of filling gaps with assumptions.
- Review claims and editorial quality. Check factual support, usefulness, language, structure, and brand requirements.
- Validate the publishing package. Check HTML, metadata, links, images, categories, and destination settings.
- Approve and schedule. Allow a separate publishing component to act only after the required approvals are present.
Define what each handoff must contain
Each stage should produce a predictable result. A brief might contain an audience description and approved angle. A draft should include content plus a claim list. A review should identify specific blocking issues rather than return an ambiguous instruction such as “make this better.”
Consider an illustrative article about a software integration. The research stage supplies supported setup requirements. The drafting stage explains the process. A reviewer compares every compatibility statement with the approved documentation, while the publishing validator checks that instructional screenshots have the required descriptions.
This separation helps you identify the actual source of a failure. If the evidence package omitted an important limitation, replacing the drafting model is unlikely to solve the underlying problem.
It also gives you a simpler alternative to full automation: automate briefs, outlines, and first drafts while retaining manual editing and publication. That can be a sensible starting point when the workflow is not yet stable.
Build a model router around explicit task policies
A model router is the component that turns an editorial task into a request to an approved model. It should use maintained configuration rather than model names scattered throughout scripts, prompts, plugins, and publishing jobs.
Use internal role names such as outline_writer, draft_writer, and editorial_reviewer. Map those roles to actual model identifiers in one configuration layer. Changing the mapping then becomes a controlled operational change rather than a search through the entire application.
Route by requirements, not model reputation
For each role, document the minimum capabilities the task requires. Relevant criteria include the amount of source material, structured-output needs, tool access, expected response time, and the editorial consequences of a mistake.
- Candidate lightweight tasks: Suggesting titles from an approved brief, classifying articles into an existing taxonomy, or proposing meta descriptions from finished content.
- Candidate complex tasks: Reconciling conflicting source passages, restructuring a difficult draft, or reviewing a technical argument against supplied evidence.
- Non-model tasks: Checking required fields, validating HTML structure, detecting duplicate publishing jobs, and enforcing publication permissions.
These are starting hypotheses, not guarantees about model quality. A less expensive model may perform adequately on a tightly constrained drafting task, while a seemingly simple classification job may become difficult when the taxonomy is ambiguous. Your evaluation results should decide the assignment.
Keep provider differences behind an adapter
A provider adapter translates your internal request into the provider’s supported API format and normalizes the response. Keep provider-specific message formats, tool definitions, error handling, and authentication out of the editorial workflow wherever practical.
The adapter should preserve important differences rather than pretend that every model supports identical features. If a task requires a particular tool or output constraint, the router should reject models that cannot meet that requirement.
Record the selected provider, model identifier, prompt version, source-package version, and task outcome with each run. This makes it possible to investigate whether a quality change came from a model rotation, an edited instruction, or different input material.
Finally, keep the routing policy understandable. A small set of explicit rules is easier to test than a second AI system making unrestricted model-selection decisions. Add dynamic routing only when you can explain the decision and measure whether it improves the workflow.
Ground drafts in evidence before adding SEO polish
A stronger model is not a substitute for reliable source material. If you want factual articles, give the workflow a defined evidence package and make unsupported claims a blocking issue rather than a stylistic concern.
HCLTech’s whitepaper on governed generative AI content emphasizes trusted source material, bounded generation, and human review. Applied to blogging, that means specifying what the model may use, what it must not infer, and who is accountable for approving the result.
Create a source package the reviewer can inspect
Store the source title, location, relevant excerpt, and the claim it supports. Where freshness matters, include the date on which your team retrieved or verified the material. Do not ask the model to invent a citation when a source is missing.
For example, a product announcement can support a statement that a feature was announced. It may not establish that the feature is enabled for every customer, supported in every region, or available under every subscription. Those broader statements need their own evidence.
- Require support for numbers, dates, availability claims, comparisons, and attributed statements.
- Separate sourced facts from recommendations, hypothetical examples, and editorial judgments.
- Flag conflicting or incomplete evidence for review instead of silently choosing the most convenient version.
- Check that a source supports the exact wording of a claim, not merely the general topic.
Use model review as assistance, not proof
A reviewing model can compare a draft with supplied passages and identify apparent gaps. It cannot establish a claim merely by agreeing with the drafting model. Even independent model outputs can repeat the same unsupported assumption.
For material that depends on current external information, the workflow needs an approved retrieval process or human verification. If neither is available, narrow the statement, remove it, or hold the article.
Apply SEO editing after the article has a defensible factual foundation. Ask the SEO stage to improve ings, relevance, internal-link suggestions, and search-result copy without adding new factual claims. This prevents an optimization pass from undoing the constraints imposed during research.
Keyword coverage should help the reader navigate the subject. It should not turn a clear article into a collection of repeated phrases or encourage unsupported claims simply because they might match a query.
Connect AI content generation to WordPress safely
Content generation and content publication should be separate capabilities. The component that writes an article does not need unrestricted authority to publish it, change site settings, or modify unrelated posts.
WordPress.com has announced AI-agent capabilities for creating, editing, and managing content. The WordPress.org plugin ecosystem also includes AI writing and auto-posting workflows, including queued generation features. These options establish that integrations exist, but they do not establish that every installation provides the same controls.
Choose an integration based on control requirements
A plugin may be suitable when you want an interface inside WordPress and your workflow fits its supported features. An external orchestration service may be more appropriate when you need custom model routing, evidence storage, approval rules, or detailed execution records.
Before choosing either approach, inspect how it handles credentials, draft status, scheduling, retries, and updates. WordPress.com capabilities and those of a self-hosted WordPress installation are not interchangeable; confirm what your actual site and integration support.
- Create a publishing package. Include the approved HTML, title, slug, excerpt, metadata, and any required taxonomy or media information.
- Validate the package. Reject missing required fields, malformed markup, unapproved links, and content that still contains unresolved editorial notes.
- Save a draft. Record the returned content identifier so later operations update the intended post.
- Review the rendered page. Check ings, lists, links, images, and layout in the destination theme.
- Schedule only after approval. Confirm the intended publication time and site time zone before changing publication status.
Use the narrowest permissions your integration supports. Keep secrets out of prompts and generated content, and do not allow text inside a source document to redefine publishing instructions.
Prevent duplicate and partial publishing actions
Give each article job a stable identifier and store its publishing state. Before retrying a request, determine whether the previous attempt already created the draft. Otherwise, an uncertain network response can become duplicate content in your queue.
Keep a record of the last approved version so an editor can restore it if a later update introduces a problem. A successful API response is not the same as a successful editorial outcome; the rendered article still needs to match the approved package.
Plan model migrations before a model is retired
Model rotation becomes easier when migration is treated as routine maintenance rather than an emergency. Maintain an inventory of the models used by each workflow, the features they depend on, and the person responsible for approving replacements.
Anthropic’s deprecation guidance says customers with active deployments receive at least 60 days’ notice before retirement of publicly released models. Its migration documentation also describes changes to legacy interfaces and clients. The operational lesson is to track both model availability and integration compatibility.
OpenAI’s model catalog and migration guidance likewise make explicit model selection important. A model identifier is a dependency, and changing that dependency can require more than editing a name in configuration.
Use a repeatable migration sequence
- Read the provider’s guidance. Check supported inputs, output behavior, tools, parameters, and client requirements.
- Update the adapter in a test environment. Confirm that authentication, request formatting, response parsing, and error handling still work.
- Run representative editorial tasks. Evaluate the replacement against the same briefs and source packages used for the incumbent.
- Review differences. Examine factual support, instruction following, tone, formatting, latency, and total workflow cost.
- Release to a limited queue. Keep publication review in place while observing the replacement on real inputs.
- Promote or revert. Update the approved mapping only after the release criteria are met.
A replacement model can return valid text while still changing your workflow’s behavior. It might produce longer introductions, interpret source restrictions differently, or format structured fields in a way your parser does not expect. Test the whole path rather than only checking that an API call succeeds.
Choose within-provider or cross-provider rotation deliberately
Rotating within a provider may let you retain more of the existing integration. Moving between providers can require additional work around tools, request formats, and output expectations. Neither approach removes the need for editorial evaluation.
Cross-provider fallback can be useful when provider diversity is an explicit requirement. It also creates another system to configure, monitor, and approve. Do not assume that two models are interchangeable because both can write a fluent paragraph.
Keep the previous working configuration available when it remains supported. If it is no longer available, the safe fallback may be to pause publication and continue collecting drafts rather than switch automatically to an untested model.
Evaluate model quality with your own publishing tasks
General model descriptions help you form a shortlist, but your publishing workload should determine whether a model is approved. Build a reusable evaluation set from the kinds of articles and editorial problems your team actually handles.
Include ordinary assignments and difficult cases. A workflow that performs well on a straightforward overview may fail when sources disagree, a brief contains exclusions, or a draft must distinguish product documentation from marketing language.
- A constrained brief: The article must answer a specific question without expanding into unrelated topics.
- An evidence gap: A requested claim has no supporting source and should be flagged or omitted.
- A conflicting-source case: The model must identify the conflict rather than combine incompatible statements.
- A formatting task: The output must satisfy the exact fields and HTML rules expected by your publisher.
- An editorial revision: The model must improve clarity without introducing new claims or changing the intended meaning.
Separate blocking failures from preferences
Unsupported factual claims, missing required disclosures, broken output structure, and unauthorized publishing actions should not be traded against elegant prose. Treat them as blocking failures.
Other qualities can be assessed through an editorial rubric: clarity, depth, repetition, audience fit, ing usefulness, and the amount of human revision required. Keep those criteria explicit so reviewers are not simply choosing the prose style they personally prefer.
Where practical, have editors assess outputs without seeing the model name. Record their reasons, not just a winner. A note that an output omitted a prerequisite is more useful for debugging than a vague judgment that it felt weaker.
Change one major variable at a time
When comparing models, hold the brief, evidence, and instructions stable. If you change the prompt and model together, it becomes harder to determine what caused an improvement or regression.
After selecting a candidate, test any model-specific prompt adjustments separately. Keep a versioned record of those instructions so you can reproduce the conditions under which the model was approved.
Repeat evaluations when the model, prompt, source process, or publishing integration changes materially. Evaluation is not a one-time certificate; it is the mechanism that makes rotation controlled rather than speculative.
Control cost, latency, and fallback behavior together
The least expensive generation request is not necessarily the least expensive publishing workflow. A draft that requires repeated rewrites, extensive editing, or troubleshooting may cost more overall than one produced by a model with a higher request price.
Measure cost at the article and workflow level. Include drafting, review calls, retries, retrieval, and human editing time where you can track them consistently. Evaluate latency in the same way: the relevant measure is often time to an approved draft, not time to the first response.
Put limits around automated revision
A revision loop needs a stopping rule. If a draft repeatedly fails the same evidence check, asking another model to rewrite it may only produce a more polished version of the same unsupported claim.
- Set a maximum number of automated revision attempts for each stage.
- Return specific validation errors to the responsible stage rather than regenerating the entire article by default.
- Escalate missing evidence to research or an editor, not merely to a more capable writing model.
- Reuse approved intermediate work when the brief and source package have not changed.
Distinguish operational failures from editorial failures. A temporary service error may justify a retry or approved fallback. A factual-support failure requires a content decision. Treating both as generic errors can turn infrastructure resilience into uncontrolled rewriting.
Define what happens when no approved model is available
A fallback policy should identify eligible tasks, approved alternatives, and conditions that stop the workflow. A model approved for metadata should not automatically inherit responsibility for technical review because the preferred reviewer is unavailable.
For scheduled content, keep an approved publishing queue where appropriate. If generation is interrupted, already approved articles can remain separate from incomplete work. Do not lower the editorial threshold merely to fill a slot.
Monitor failure reasons as well as spending. Repeated formatting errors suggest a different intervention from repeated source gaps. Good operational records help you decide whether to adjust the model, the instructions, the source collection process, or the integration.
Roll out automation gradually, then repurpose approved content
Introduce automation in stages so you can observe failures before they reach readers. Begin with a narrow article category whose sources, structure, and review requirements are well understood.
For example, you might start with explanatory posts based on approved internal documentation rather than articles requiring open-ended reporting. This is an implementation choice, not a guarantee of accuracy; the same evidence and approval requirements still apply.
- Assist the existing process. Generate briefs, outlines, and metadata while editors retain control of drafting decisions and publication.
- Automate draft assembly. Connect approved evidence to drafting and review, then deliver the result to a human editor.
- Automate publishing preparation. Create draft posts, validate the rendered content, and prepare scheduling information.
- Expand only after review. Add article categories or permissions when evaluation results and operational records support the change.
Use approved articles as the source for other channels
The Canadian Marketing Association’s AI playbook describes repurposing blog content into social posts, emails, and presentations. In a governed workflow, these derivatives should come from the approved article rather than from an earlier draft or the original generation prompt.
Give each channel its own constraints. A social post may need a concise statement and a link; an email may need context for a different audience. Shortening the content must not remove a qualification that changes the meaning of the claim.
Model rotation can apply here too. A constrained repurposing task may use a different approved model from the one used for the original article. Evaluate whether it preserves the article’s meaning instead of judging only whether the result sounds engaging.
Assign ownership after launch
Name an owner for editorial quality, model configuration, and publishing operations, even if one person initially covers all three. Someone must respond when a source changes, an integration fails, or a provider announces a retirement.
Track corrections and editor feedback alongside technical logs. Those records reveal problems that successful API calls cannot: repetitive explanations, omitted limitations, misleading summaries, or content that answers the wrong reader question.
The workflow is ready to expand when its decisions are understandable and its failures are recoverable. More automation should follow demonstrated control, not substitute for it.
To automate blog publishing with AI model rotation, start with a defined editorial pipeline, explicit task-to-model assignments, and evidence-based review. Keep model configuration separate from business logic, test replacements before deployment, and reserve publication authority for a controlled final step.
Begin by mapping one article type from brief to scheduled post. Build a small evaluation set, approve a primary model and any necessary fallback for each role, and run the process in draft-only mode until you can reliably explain what passes, what fails, and who makes the final decision.